Your workflow becomes the test.
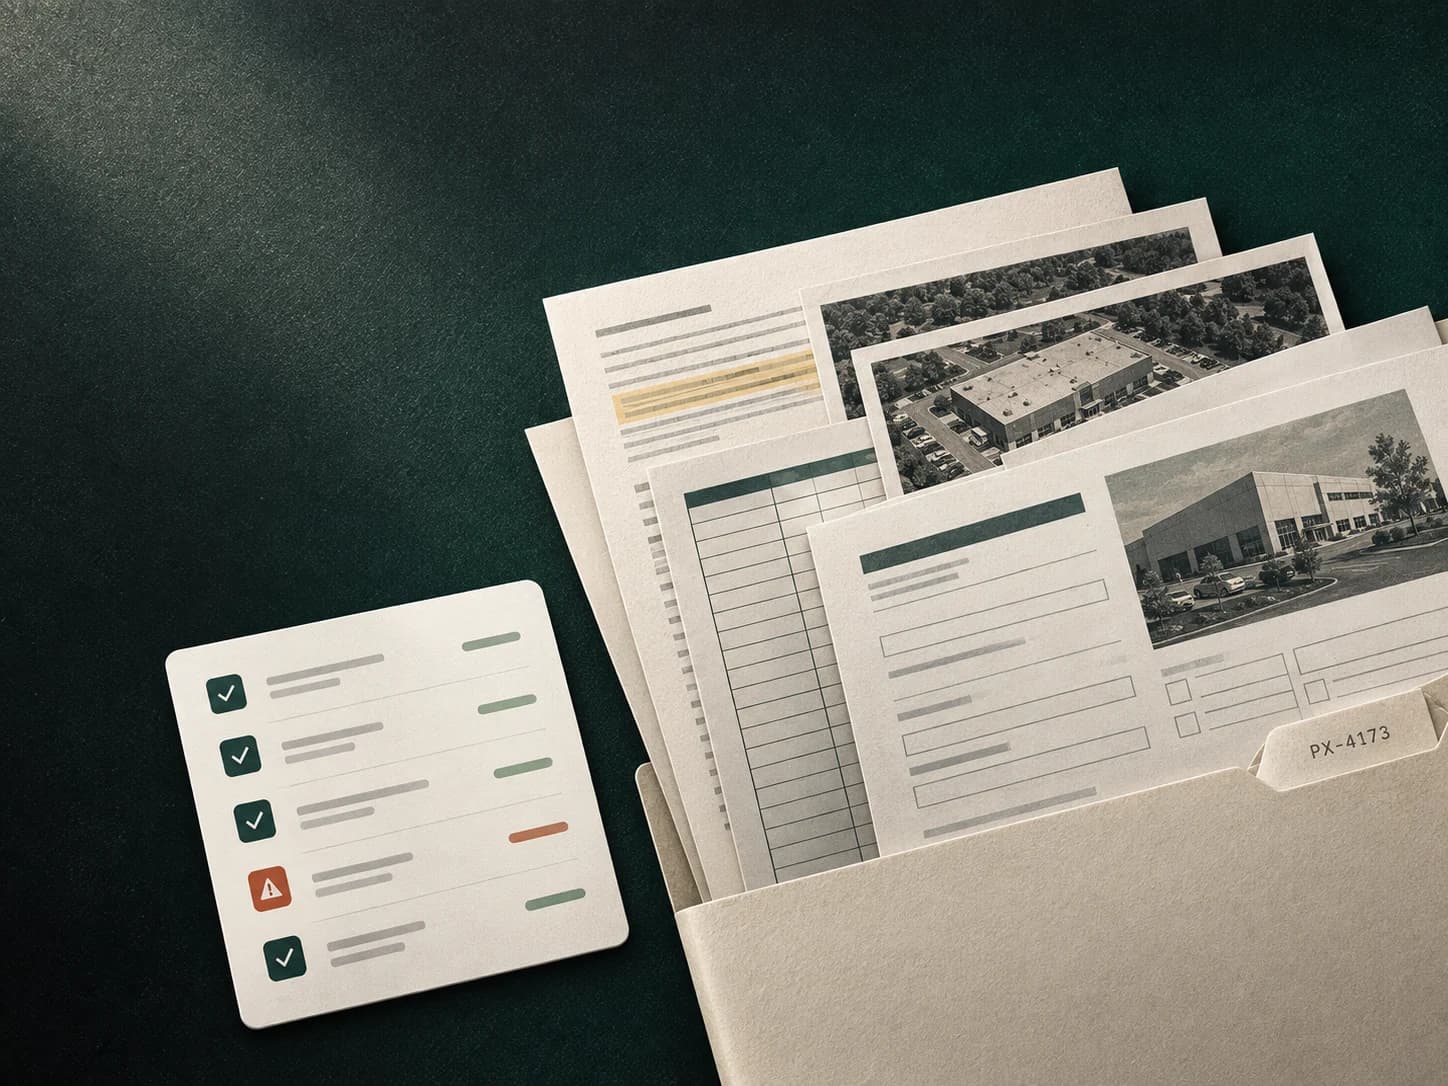
Claim files, submissions, policy documents, and your systems, rebuilt as an environment an agent can act in.
Private evaluation and training for insurance agents, from claims to underwriting. Built around your policies, guidelines, tools, and cases to measure reliability before deployment.
We rebuild your workflow as a private environment, run the agent through it again and again, and grade every decision on three measures.
Claim files, submissions, policy documents, and your systems, rebuilt as an environment an agent can act in.
Did the agent read the right evidence, apply the right rule, and reach a supported decision?
Does the same case get the same decision, run after run?
Can it hold that standard without excess tool calls, retries, cost, or human rework?
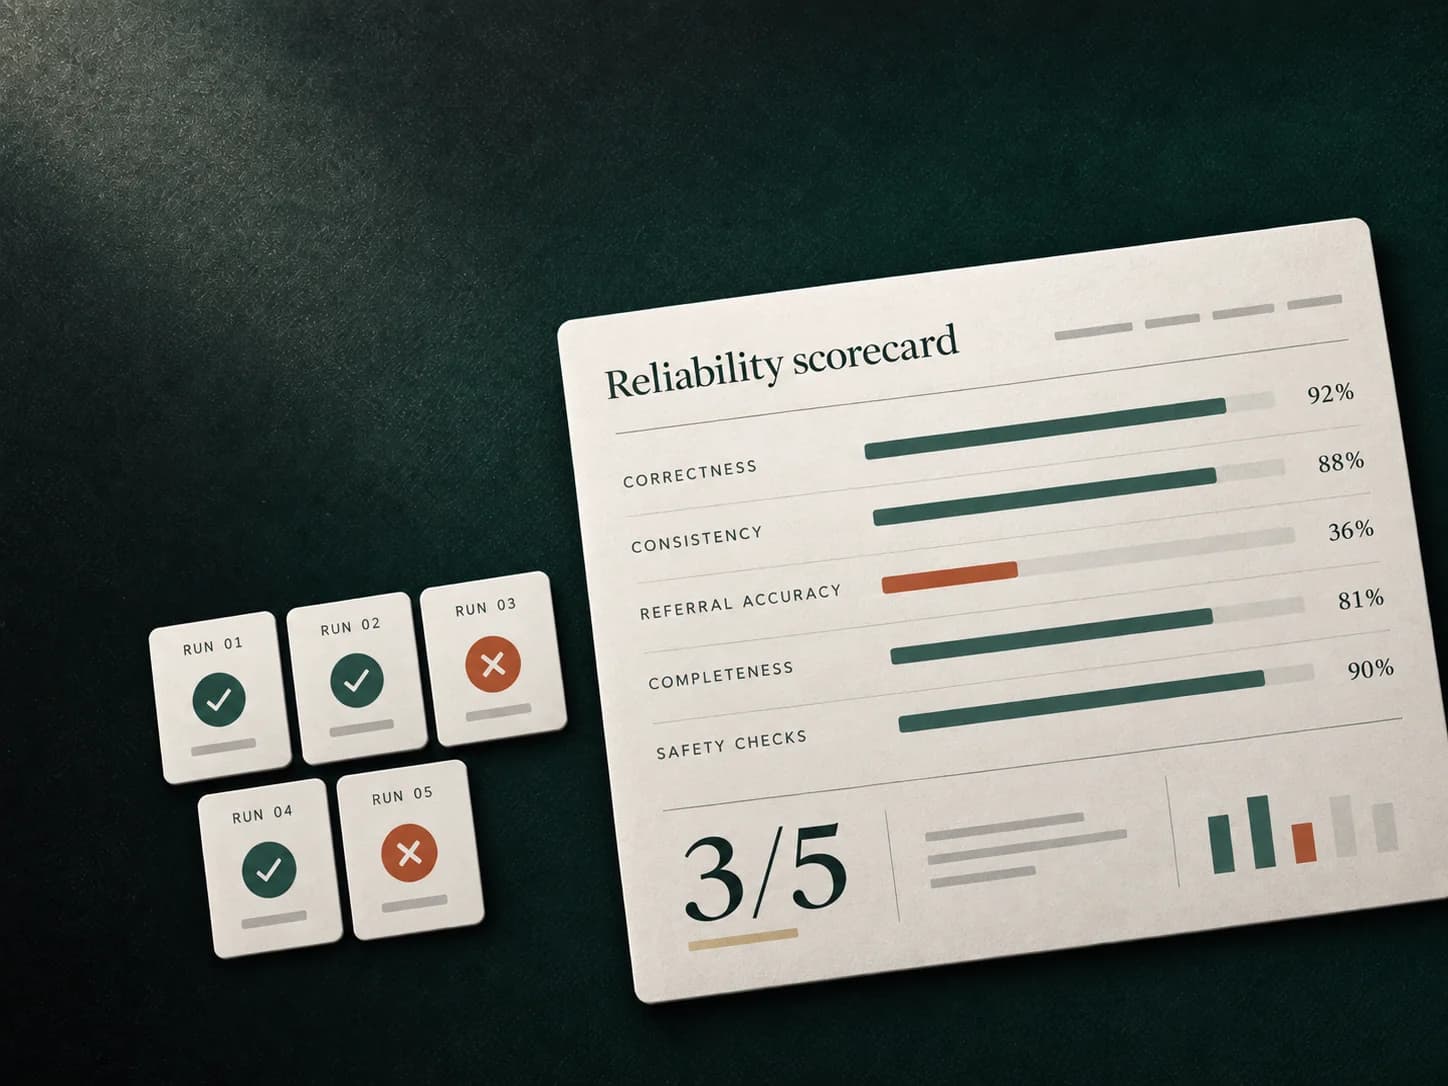
One good run proves little. Five show whether the agent holds.
| Run | Recommendation | Guideline applied | Referral | Tool calls | Result |
|---|---|---|---|---|---|
| 01 | Refer | §4.7 | Correct | 9 | PASS |
| 02 | Accept | Missed §4.7 | Missed | 7 | FAIL |
| 03 | Refer | §4.7 | Correct | 14 | PASS |
| 04 | Refer | §4.7 | Correct | 8 | PASS |
| 05 | Accept | Missed §4.7 | Missed | 11 | FAIL |
Nothing about the risk changed. The agent did.
Your policies, guidelines, and cases, rebuilt as a private environment for claims or underwriting agents.
Correctness, consistency, and referral accuracy, measured across repeated runs of the same case.
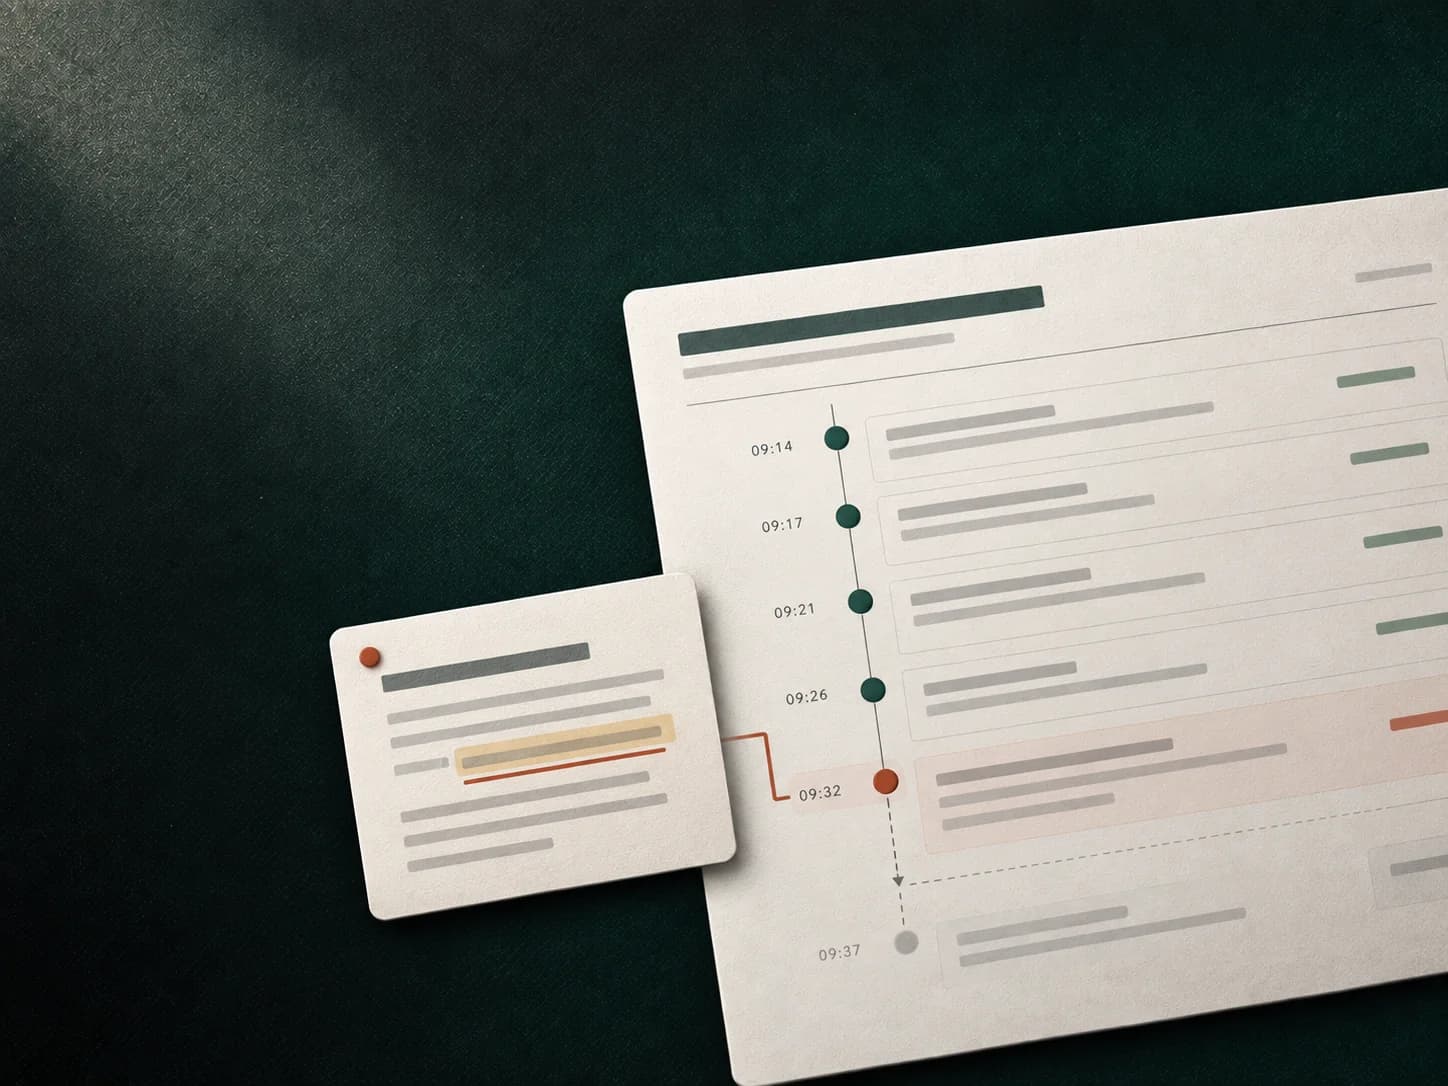
See exactly where a run diverged: the evidence it missed, the rule it misapplied, the referral it skipped.
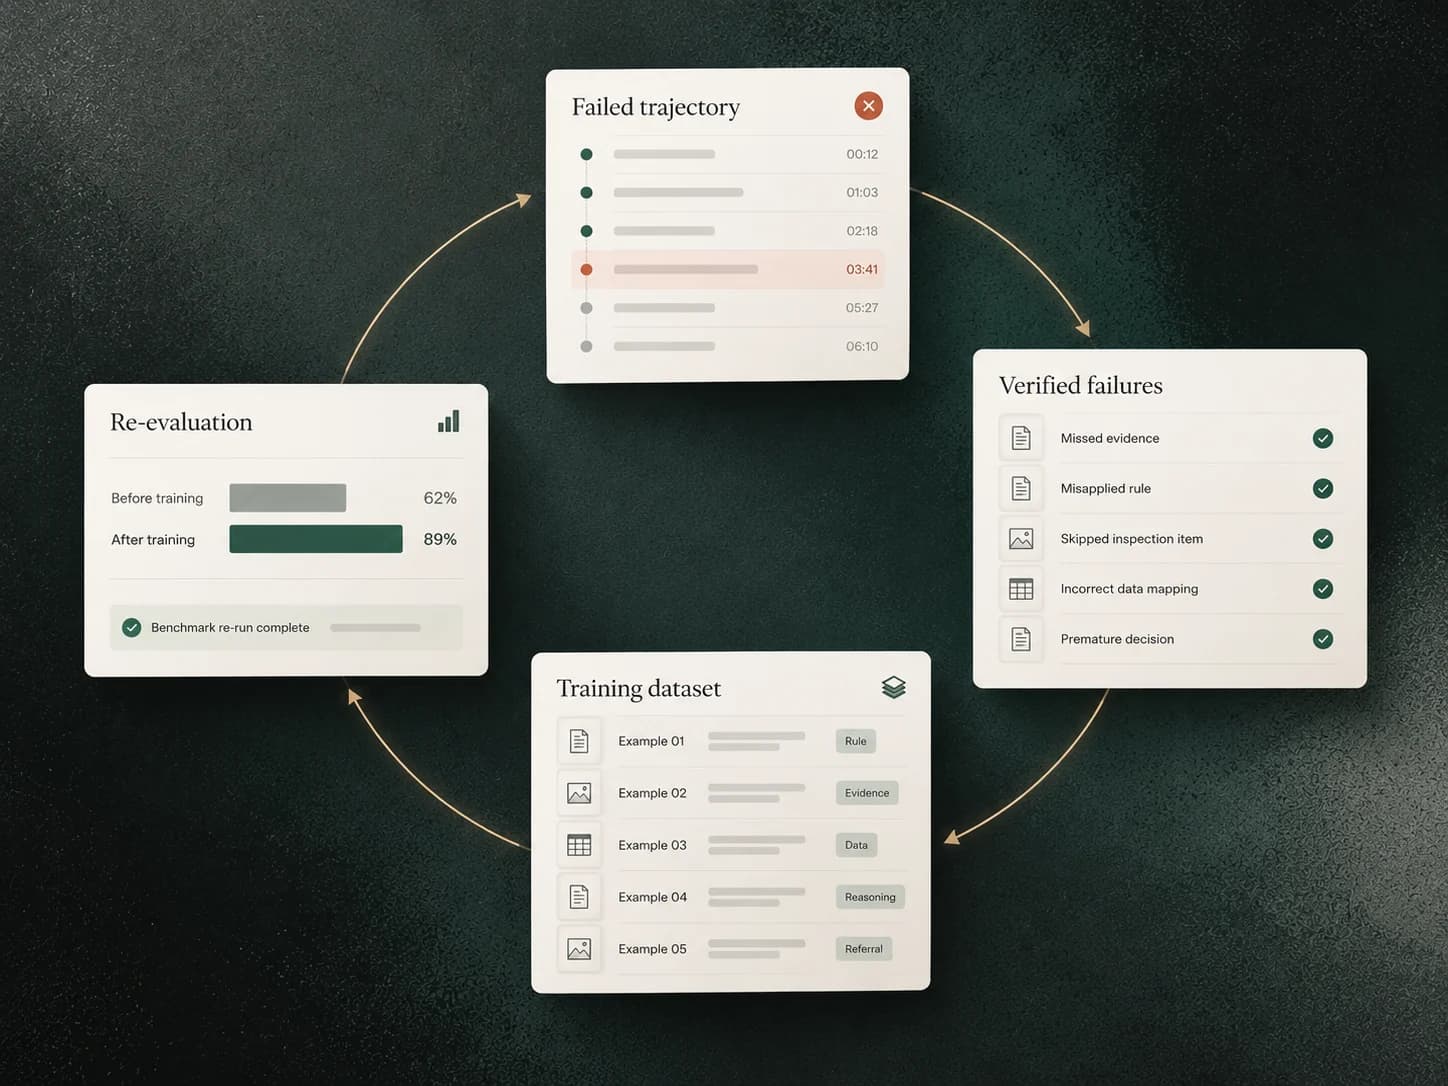
Verified failures become targeted post-training data, then the same benchmark runs again.
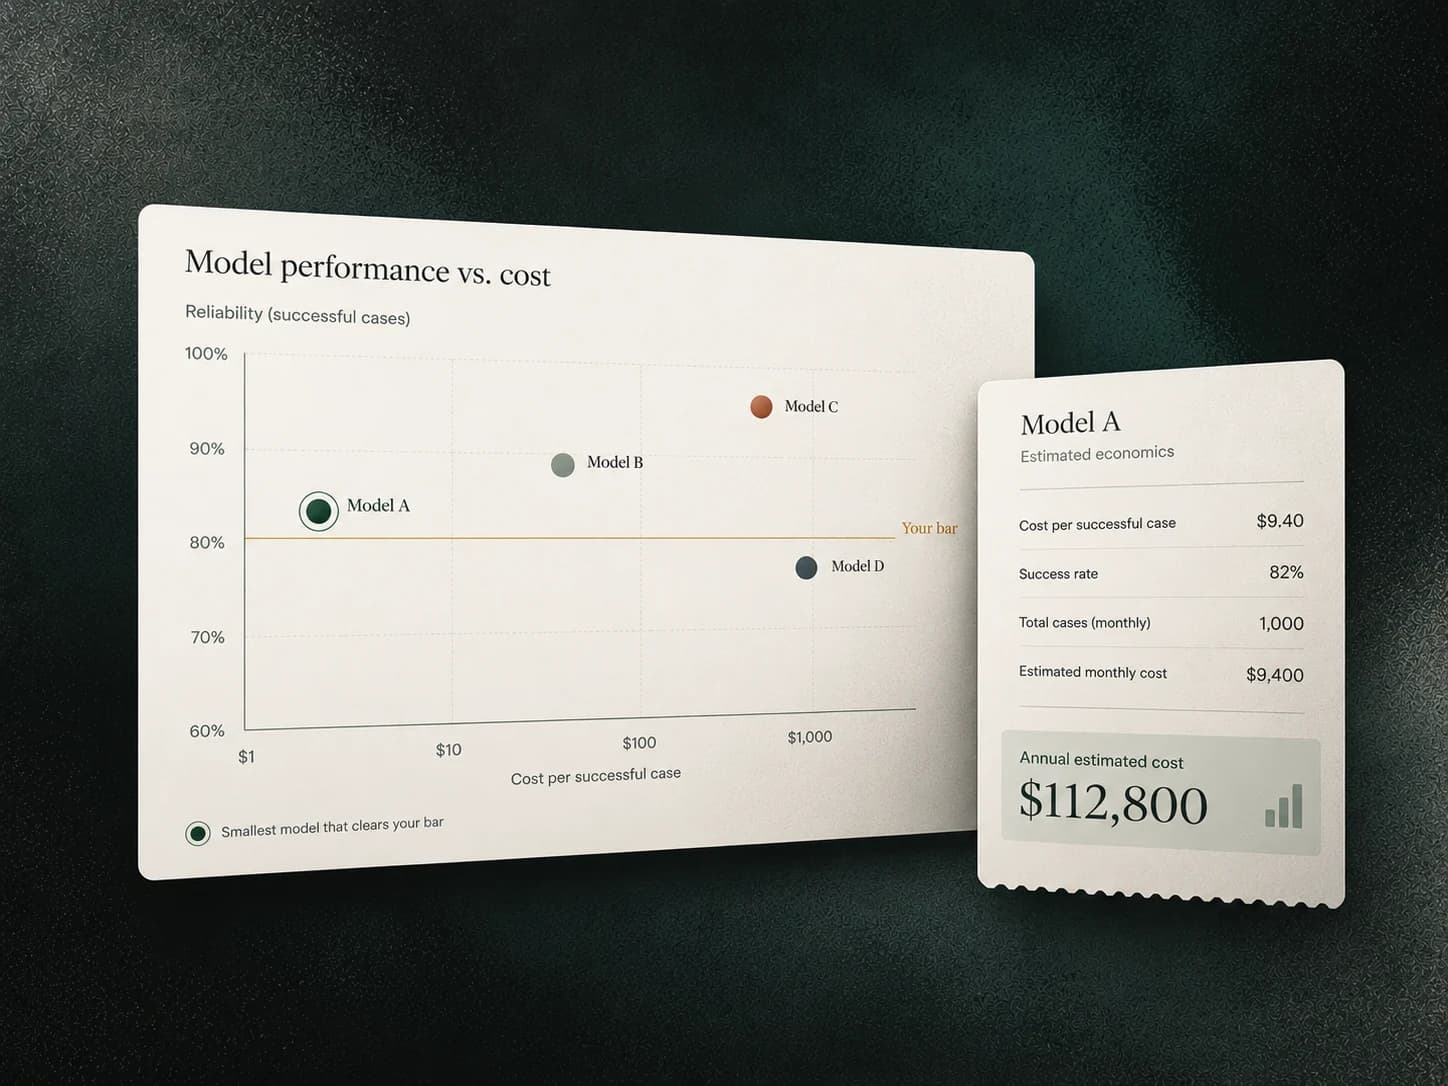
Find the smallest model that clears your bar, priced per successful case rather than per token.
Where insurance agents break down, and what it takes to measure and fix it.
Twelve model configurations tested on evidence, rules, and completed work.
Benchmark
Repeated runs reveal whether underwriting agents apply the same rules consistently.
Research
Thirty fictional claims test investigation, coverage decisions, payments, and disputes.
Benchmark